Guide
Installation, model download, building the engines and starting the server.
Requirements
- AMD Strix Halo (gfx1151) with 128 GB, Linux with ROCm/HIP 7.x,
cmake,ninja,git. - Kernel parameters
amd_iommu=off amdgpu.gttsize=126976 ttm.pages_limit=32505856, so that the GPU may use almost all of the RAM. - Python 3.12+, uv, the Hugging Face CLI
hf, around 200 GB of free NVMe space.
Installation
# 1. Program
git clone <Repo-URL> qwen38-flash && cd qwen38-flash
uv sync

# 2. Model and MTP head
hf download unsloth/Qwen3.8-Flash-Next-GGUF --include 'UD-Q4_K_XL/*'
hf download dzannotti/Qwen3.8-Flash-Next-MTP-GGUF Qwen3.8-Flash-Next-MTP-Q4_K_M.gguf

# 3. Engines
engine/fetch.sh            # fetch and patch llama.cpp + EngramHalo.cpp
engine/build-engramhalo.sh # recommended engine
engine/build.sh hip        # second engine

# 4. Start
./run.sh                   # terminal program, preset eh-qualitaet (highest quality), F5
Recommended command line (without the program)
ROCBLAS_USE_HIPBLASLT=1 engine/build-engramhalo/bin/llama serve \
  -m .../UD-Q4_K_XL/Qwen3.8-Flash-Next-UD-Q4_K_XL-00001-of-00004.gguf \
  -ngl 99 -c 131072 -fa on -ctk q8_0 -ctv q8_0 -b 8192 -ub 2048 -t 4 -lm none \
  -md .../Qwen3.8-Flash-Next-MTP-Q4_K_M.gguf -ngld 99 \
  --spec-type draft-mtp,ngram-mod --spec-draft-n-max 4 --spec-draft-p-min 0.75 \
  --jinja --chat-template-kwargs '{"reasoning_effort":"medium"}' \
  --temp 1 --top-p 0.95 --top-k 20 --min-p 0 \
  --host 0.0.0.0 --port 8080 --metrics
For several users: set -np 8 (the context then applies to all slots together) and leave out the three MTP lines.
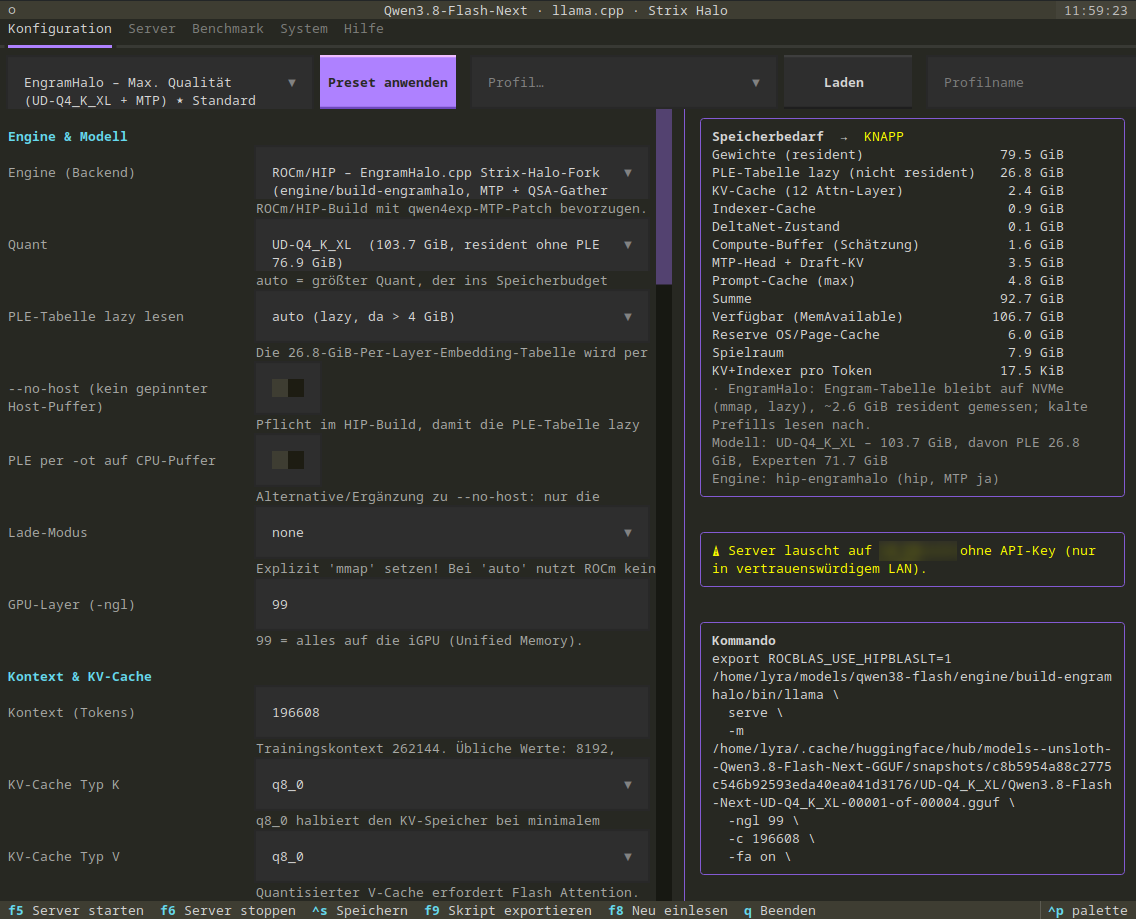
Presets in the program
| Preset | Engine | Quant | Context | MTP | Purpose |
|---|---|---|---|---|---|
| eh-qualitaet (default) | EngramHalo | UD-Q4_K_XL | 131072 | on | best quality, one user |
| eh-no-thinking | EngramHalo | UD-Q4_K_XL | 131072 | on | chat and tools without thinking |
| eh-schnell | EngramHalo | UD-IQ3_XXS | 32768 | on | smallest footprint |
| eh-longctx | EngramHalo | UD-IQ4_XS | 163840 | on | long documents |
| eh-agent | EngramHalo | UD-Q4_K_XL | 163840 | on | coding agent, one slot, room for containers |
| eh-team | EngramHalo | UD-IQ3_XXS | 8 × 196608 | on | several agents at once, one slot each |
| stock-* | llama.cpp + patch | IQ4_XS / IQ3_XXS / Q2_K_XL | depends on preset | on | fallback without EngramHalo |
Troubleshooting
- Kernel OOM: check the memory balance in the program (at least 8 GB of headroom), choose a smaller quant or context, stop other LLM processes.
- Loading takes hours:
--load-mode mmapon the stock fork. Set the load mode to auto or use EngramHalo. - MTP head does not load: the unsloth head was chosen. Use the dzannotti head.
- Unexpected reasoning effort: only xhigh, medium, low are allowed.